How Applicant Tracking Systems (ATS) Actually Parse Resumes: The 2026 Technical Guide
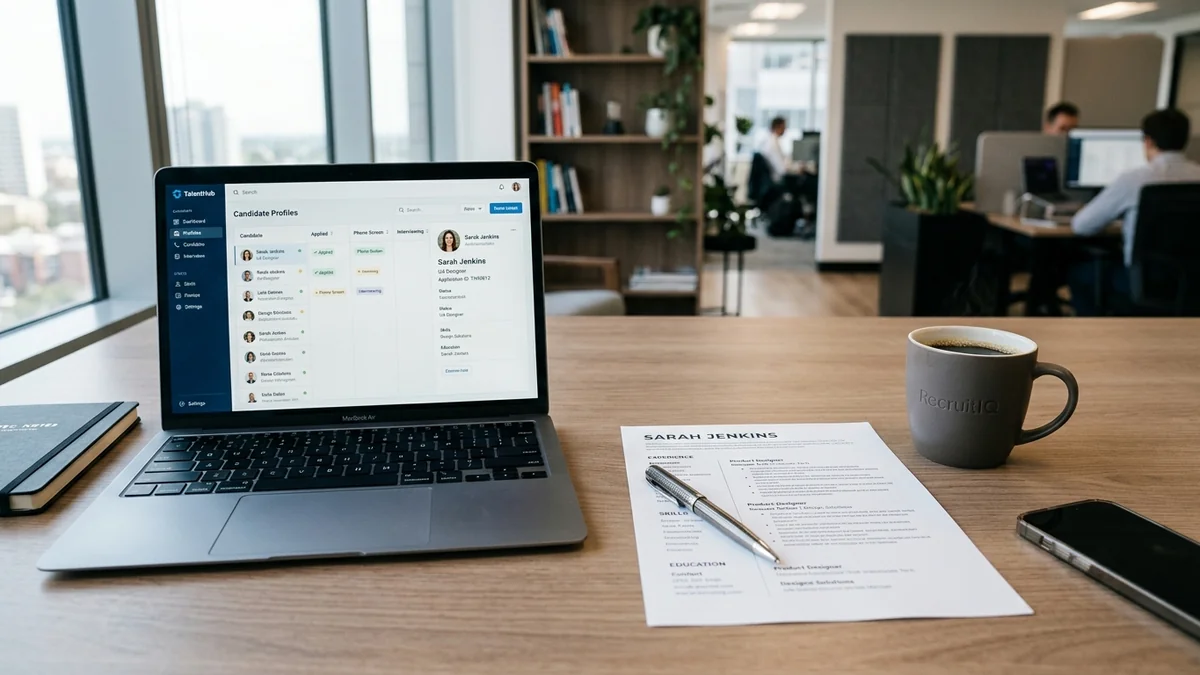
The Reality Behind Modern Applicant Tracking Systems
Every year, thousands of job seekers submit resumes that vanish into an apparent digital void. A widespread misconception is that an artificial intelligence algorithm ruthlessly deletes 75% of applications without a human ever seeing them. While the rejection rate is real, the mechanism is misunderstood. An Applicant Tracking System (ATS) is not an autonomous gatekeeper; it is a document ingestion database and recruitment workflow tool used by corporate recruitment teams to organize hundreds of incoming applications per job requisition.
Enterprise recruitment suites such as Workday, Greenhouse, Lever, Taleo, and BambooHR rely on specialized document parsers (including Sovren, Textkernel, and modern natural language processing models) to transform unstructured PDF and Word files into structured relational database profiles. When a parser encounters unconventional layouts, graphical tables, or embedded text layers, candidate information becomes corrupted or omitted from the recruiter's search index.
1. How Ingestion Engines Process Your Document
To design a resume that passes parser ingestion reliably, candidates must understand the three sequential phases of document extraction:
- Plain-Text Extraction: The engine strips away visual styling, margins, and layout coordinates to read linear text streams. Resumes created in vector graphics programs where text has been outlined into paths or flattened into raster graphics result in empty text layers. To an ATS, a graphical resume is functionally equivalent to submitting a blank sheet of paper.
- Entity Recognition & Hierarchy Classification: Natural Language Processing (NLP) models identify entity boundaries: contact details, date ranges, employer names, and standard section headers. Using standard headings such as "Professional Experience", "Education", and "Core Competencies" ensures the parser assigns records to the correct database fields. Ambiguous headings like "My Professional Journey" or "Milestones" frequently cause parsing algorithms to misfile employment history under miscellaneous notes.
- Semantic Taxonomy Alignment: Modern ATS engines no longer look exclusively for verbatim keyword strings. They cross-reference industry skill ontologies. For example, if a job requisition lists "Cloud Infrastructure", the semantic parser identifies related competencies such as "AWS, Terraform, Docker, and Kubernetes", attributing relevance to the applicant's profile even without exact phrase repetition.
2. Core Formatting Standards for 100% Ingestion Accuracy
Achieving reliable parser ingestion does not require an unattractive, unstyled plain-text file. It requires adherence to predictable structural hierarchy:
| Formatting Element | Parser-Compliant Standard | High-Risk Formatting to Avoid |
|---|---|---|
| File Format | Selectable text PDF or clean Microsoft Word (.docx). | Multi-layer Illustrator/Photoshop exports or image formats (.png, .jpg). |
| Document Layout | Single-column top-to-bottom vertical structure. | Multi-column sidebars, floating text boxes, and nested tables. |
| Contact Coordinates | Placed directly in the primary body flow at the top of page 1. | Placing phone numbers or emails inside Microsoft Word header/footer zones. |
| Skill Proficiency | Text lists: "Python (Advanced), SQL (Intermediate)". | Graphic rating stars, circular percentage meters, or icon bar graphs. |
| Section Dividers | Standard horizontal borders applied via paragraph rules. | Drawn vector graphic lines or background colored fill blocks. |
3. Strategic Keyword Integration Without Algorithmic Manipulation
Keyword optimization is frequently confused with keyword stuffing: the outdated practice of copying the entire job advertisement in white 1pt font into the footer. Modern parsers flag hidden or color-matched text immediately, prompting automated rejection flags for deceptive practices.
A legitimate, high-converting keyword integration approach follows three principles:
- Deconstruct the Target Job Requisition: Group required competencies into three buckets: Tools & Technologies (e.g., SAP, Salesforce, Power BI), Methodologies (e.g., Agile Scrum, Lean Six Sigma), and Regulatory / Compliance Standards (e.g., IFRS, GDPR, KRA statutory compliance).
- Incorporate Competencies into Quantified Bullets: Do not relegate critical skills to a standalone, uncontextualized list at the bottom. Demonstrate active execution: "Utilized Power BI and SQL to automate weekly sales funnel analytics across 14 retail branches, reducing inventory reporting cycles by 12 hours."
- Provide Both Acronyms and Full Phrasing: Recruiters search using varied terminology. Include both variations: "Certified Public Accountant (CPA-K)" or "Search Engine Optimization (SEO)" to capture both search queries.
4. Step-by-Step ATS Self-Audit Procedure
Before submitting an application through any enterprise portal, perform this 5-minute technical pre-flight check:
- The Raw Text Selection Test: Open your PDF document in a browser or PDF reader. Press
Ctrl+A(orCmd+A) to select all text, copy the contents, and paste them into a basic text editor such as Notepad. Inspect the pasted output. If your job titles merge into dates, if sidebars appear interleaved between work history bullets, or if whole sections disappear, an ATS parser will encounter identical extraction errors. - Standardizing Naming Conventions: Save your submission file using a clean, readable standard:
FirstName_LastName_TargetRole_CV.pdf. Avoid ambiguous names likeUpdated_Resume_Draft_v3.pdf. - Pre-formatted Semantic Structure: If you prefer to avoid manual formatting errors, build your document using Center Board's AI CV Builder, which formats every section according to single-column ATS semantic guidelines.
Technical Deep Dive: PDF Text Streams and Character Encoding
A frequent reason resumes fail ATS parsing is hidden character encoding corruption. When exporting from word processors or design software, certain fonts utilize custom ligatures (e.g., combining 'fi' or 'fl' into a single typographic glyph). While visually pleasing to human eyes, primitive PDF text extraction libraries convert these ligatures into null characters or replacement question marks, causing words like 'financial' to parse as 'nancial'. This prevents keyword matching for that term entirely.
To avoid character corruption, adhere to these technical document standards:
- Standard Unicode Fonts: Restrict your typography to universally supported typefaces: Inter, Arial, Calibri, Helvetica, Georgia, or Times New Roman. Avoid custom downloaded icon fonts.
- Never Use Tables for Alignment: Many job seekers use invisible borderless tables to position dates and locations on the right. When an ATS parser reads cell coordinates, it reads row-by-row or column-by-column, often interleaving dates from column two into job descriptions from column one. Use tab stops or standard right-aligned paragraph tabs instead.
- Recruiter Boolean Search Syntax: Recruiters typically search ingested pools using boolean logic. For example:
("Financial Controller" OR "Finance Manager") AND ("IFRS" OR "GAAP") AND ("ERP" OR "SAP") AND NOT ("Intern"). Ensuring your core qualifications match standard industry syntax guarantees discoverability across these queries.
Real-World Autopsy: How a Senior Engineer's CV Was Rescued from Parser Failure
To illustrate how technical parsing errors occur in practice, consider the case of a Senior Infrastructure Engineer with 8 years of distributed systems experience. Despite applying to over 40 enterprise vacancies, the candidate received zero screening calls. When our team ran their original PDF resume through a commercial parser diagnostics tool, the issue was immediately apparent:
- The Multi-Column Collision: The candidate used a stylish two-column layout. The left column contained skill badges; the right column contained work history. The parser read horizontally across coordinates, producing garbled entries: "Docker Jan 2022 Senior Engineer Kubernetes managed AWS production clusters Terraform." The parser could not attribute any skill to any company.
- The Graphic Icons: Contact details were preceded by small vector glyphs (an envelope icon for email, a phone receiver for mobile). Because there was no text label, the entity extractor omitted the candidate's phone number entirely.
- The Refactored Result: We refactored the document into a single-column, standard linear layout with standard text headings ("Technical Skills", "Professional Experience") and explicit text labels ("Email:", "Phone:"). Within three weeks of resubmitting the refactored document, the candidate secured four direct recruiter screening calls.
Frequently Asked Questions
Should I submit my resume as a PDF or Word document?
Unless the application portal specifically requests a Word document (.docx), a text-based PDF generated from Word or Google Docs is standard. It preserves typography while parsing cleanly in modern recruitment systems.
Can ATS read graphics, charts, and company logos?
No. Document parsers ignore images and vector icons. If you communicate skill proficiency through visual rating bars or graphics, the parser reads zero data. Keep your skills expressed in clear text.
How do recruiters search within an Applicant Tracking System?
Recruiters apply boolean search strings such as ("Financial Analyst" OR "Accountant") AND ("IFRS" OR "GAAP") AND "SAP". Having contextual matches throughout your experience ensures your profile surfaces on candidate shortlists.
Conclusion
Passing an applicant tracking system is not about gaming an algorithm; it is about clear document engineering. When your professional accomplishments are presented in an accessible, structured format, both automated parsers and human recruiters can recognize your qualifications immediately.
Advance Your Career with Intelligent Tools
Build an ATS-ready resume in minutes, calculate your precise tax take-home pay, or explore verified vacancies from top employers across East Africa and beyond.